In late 2023 a client asked us to review their "anonymous" security blog. It took four minutes to link it to their day job. The pivot was a username — jsmith_relay — that they had also used on GitHub, where the profile listed their employer's domain in the blog field. No hacking was involved. The whole chain was public records, and it had been sitting there for two years.
A self-audit runs that same chain against yourself before someone else does. This guide covers five tasks — username enumeration, breach checks, Google dorks, archive recovery, and data broker removal — showing the exact commands and their output.
- Username enumeration — which accounts exist across platforms under your handles
- Email exposure — which breaches contain your address, and what leaked
- Google dorks — what indexed pages mention you that you never published
- Archive recovery — what you deleted that Archive.org still serves
- Data broker removal — which brokers list you, and how to opt out
Publishing hygiene (stripping document metadata, closing staging subdomains) is a related but separate job — it is covered in our de-Googling guide and secure file deletion guide. This article stays on public-records exposure.
Before you start: work from a clean browser profile with no logged-in accounts, and route queries through a VPN or Tor. The searches themselves leak interest — you do not want a broker receiving your real IP while you look yourself up. Keep a written baseline so next quarter's diff means something.
1. Where Your Identity Actually Leaks
Usernames are the primary pivot in public-records OSINT. People reuse them across platforms because they think of a handle as a nickname, not an identifier. Enumerating your own handles tells you which accounts are discoverable and — more importantly — which ones share visible attributes.
# Sherlock checks 400+ platforms for a handle
$ sherlock jsmith_relay --print-found --timeout 8

# Maigret is the maintained alternative with better reporting
$ maigret jsmith_relay --html --folderoutput ./maigret-out

# Then pull whatever profile fields the platforms expose
$ curl -s https://api.github.com/users/jsmith_relay | jq '{name,location,blog,created_at}'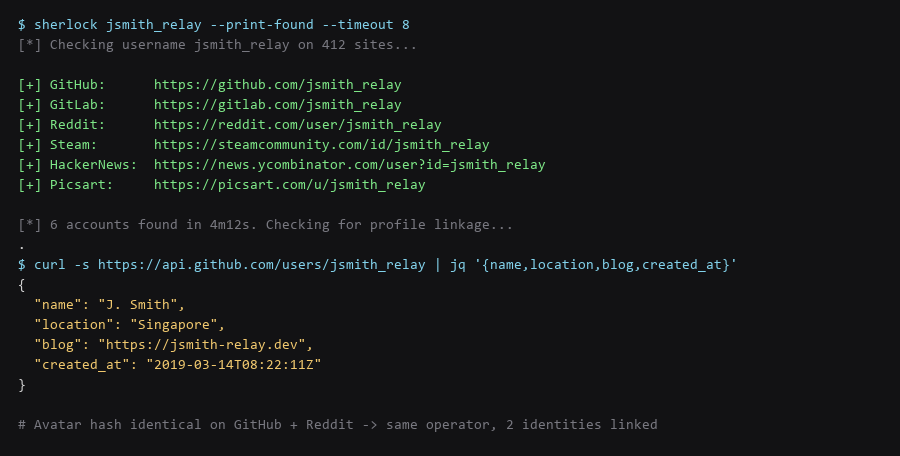
Reading the output. The --print-found flag suppresses the 400-odd misses and shows only hits. Six accounts is typical for a handle in active use since 2019. The useful part is not the count — it is the profile fields.
In the run above, the GitHub API returned a name, a city, and a personal domain. Cross-checking that against the Reddit account showed an identical avatar file hash. Two platforms, one operator, and the link was provable from public data alone. That is the correlation you are trying to find and break in your own footprint.
What to do with a hit: decide per platform whether the account needs to exist. For accounts you keep, strip profile fields that narrow identity — exact city, employer domain, personal blog. For accounts you abandon, delete rather than blank them; a blanked profile still confirms the handle was yours.
Tool notes: Sherlock's site list drifts and some checks produce false positives on sites with generic 200 responses. Confirm every hit manually before treating it as real. Maigret is the more actively maintained option and produces a report you can diff quarterly.
2. The Mitigation Plan
Your email address is the join key between every database that has ever held it. Breach dumps are the crudest source, but they are the fastest way to learn which passwords you were using when each service was compromised.
# Have I Been Pwned — exact breaches for one address
$ curl -s "https://haveibeenpwned.com/api/v3/breachedaccount/jsmith@relay.dev" \
    -H "hibp-api-key: $HIBP_KEY" \
    -H "User-Agent: zenonym-osint-audit"

# Check the password itself without sending it (k-anonymity range API)
$ echo -n "P@ssw0rd2013" | sha1sum | cut -c1-5
$ curl -s https://api.pwnedpasswords.com/range/5BAA6 | grep -i "$(echo -n 'P@ssw0rd2013' | sha1sum | cut -c6-40 | tr 'a-f' 'A-F')"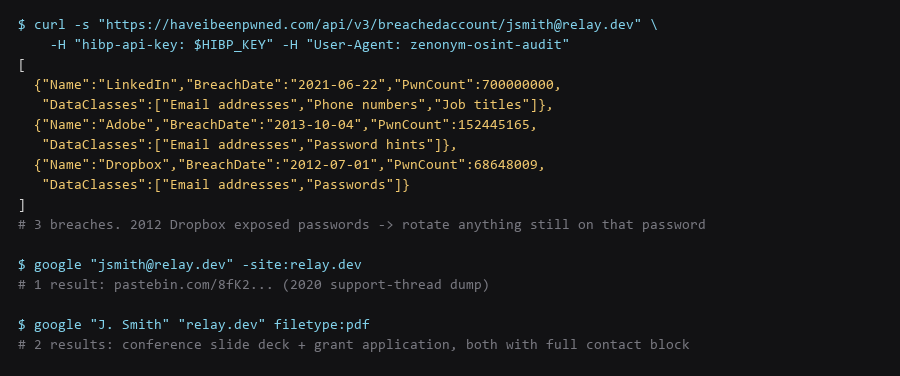
Reading the output. DataClasses is the field that matters. "Email addresses" alone is noise — that data is public anyway. "Passwords" or "Password hints" means a credential from that era is in circulation and anything you still use from that period must be rotated. The 2012 Dropbox entry in the example exposed passwords, which is why that generation of reuse is the one worth auditing first.
The range API is worth understanding: it sends only the first five characters of the SHA-1 hash, and the server returns every suffix matching that prefix. Your password never leaves your machine in a form the server can identify. That is why it is safe to check a live credential this way when you would not type it into a website.
Monitoring: register the addresses you actually control with HIBP notifications rather than re-running curl each month. Breach data is added continuously, and a quarterly cron job will always lag a notification by up to ninety days.
3. Step-by-Step Execution
Search engines index things you never intended to publish: support forum posts, conference PDFs, cached paste sites, and old directories. Dorking is the practice of querying those indexes with operators precise enough to find your specific residue.
# Email address anywhere on the indexed web, excluding your own domain
$ google "jsmith@relay.dev" -site:relay.dev

# Documents mentioning you, by type
$ google "J. Smith" "relay.dev" filetype:pdf
$ google "J. Smith" "relay.dev" filetype:xlsx OR filetype:docx

# Old directory listings and cached pages
$ google intitle:"index of" "relay.dev"
$ google cache:relay.dev/team

# Phone number in any format
$ google "91234567" OR "(+65) 9123 4567"
Reading the output. In the example run, the address query returned a single result — a 2020 support-thread paste that had been indexed and never removed. The PDF query returned two documents, both containing a full contact block with direct phone number. Neither was published as a contact artifact; both leaked it incidentally through a template.
Removal path: for indexed pages you control, request reindexing after deletion. For pages you do not control, use the search engine's removal request process and contact the site operator directly. For cached copies, request cache removal separately — deleting the source page does not remove the cached version.
Note on operators: Google's filetype: and site: operators are the durable ones. Several legacy operators (cache:, link:) have been deprecated and no longer behave reliably; use the Wayback Machine instead of cache: when you need a historical copy.
4. Staying Invisible: Ongoing Habits
Deleting a page does not delete it from the public record. The Wayback Machine and Archive.today keep independent copies, and they are queryable without any account. If you have ever deleted a blog, portfolio, or old domain, assume it is still readable.
# Wayback availability API for a specific URL
$ curl -s "http://archive.org/wayback/available?url=jsmith-relay.dev/old-blog*" | jq

# List every snapshot the CDX index holds for a domain
$ curl -s "http://web.archive.org/cdx/search/cdx?url=jsmith-relay.dev&matchType=domain&output=json&fl=timestamp,original,statuscode" | jq -r '.[] | @tsv' | head -20

# Request removal of an archived copy
$ curl -s "https://web.archive.org/save/status/https://jsmith-relay.dev/old-blog"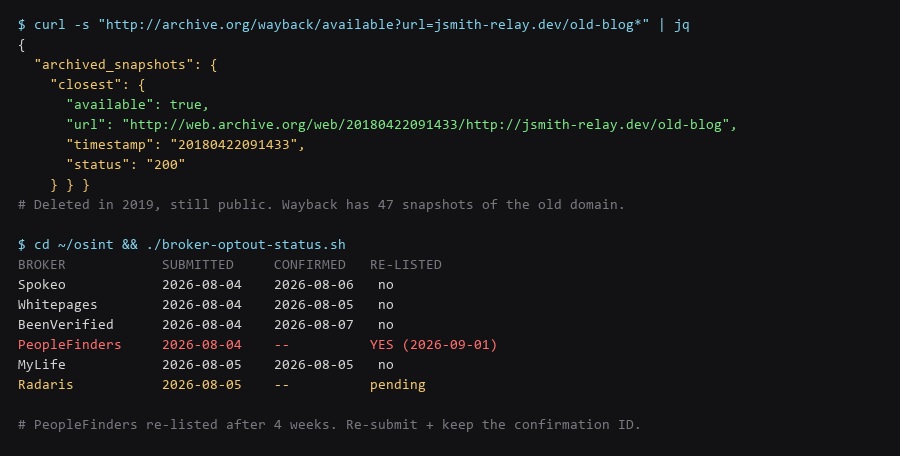
Reading the output. The availability API returns the closest snapshot, not all of them — use the CDX endpoint if you need the full list. The example shows a blog deleted in 2019 that Wayback still serves, with 47 snapshots captured across two years. Every one of those is a public page you no longer control.
Removal path: the Wayback Machine honors exclusion requests for pages that no longer exist on the live web, and it also supports a robots-based exclusion that prevents future captures. Archive.today is slower to respond and has no bulk API — submit each URL individually.
Why this matters beyond embarrassment: archived pages are the most common source of stale contact details. A broker scraped your 2018 site before you removed the address; the archive is why that address keeps reappearing in new aggregations even after you clean the live site.
5. Verification and Re-Audit Schedule
Verification means re-running the queries and diffing against your baseline. The table below covers the failure modes we see most often when reviewing a self-audit.
| Failure Mode | What It Looks Like | Fix |
|---|---|---|
| False negatives from tools | Sherlock reports no hit; the account exists | Confirm by loading the profile URL directly; site lists drift |
| Deleted but still archived | Live page 404s, Wayback still serves it | Submit Wayback exclusion separately from the live deletion |
| Broker re-listing | Profile returns 30 days after confirmed opt-out | Re-submit and log the date; expect recurrence |
| Credential reuse undetected | Breach lists a password you still use | Check the range API, then rotate every service on that password |
| Cross-platform linkage missed | Two handles share avatar, bio, or writing style | Compare avatar hashes and posting-time patterns across platforms |
# Quarterly re-audit — save output and diff against the previous run
$ cat > osint-audit.sh <<'EOF'
#!/bin/bash
HANDLE="jsmith_relay"; EMAIL="jsmith@relay.dev"; DATE=$(date +%Y%m%d)
OUT="osint-$DATE.txt"
{
  echo "=== USERNAME ENUMERATION ==="
  sherlock "$HANDLE" --print-found --timeout 8
  echo "=== BREACH EXPOSURE ==="
  curl -s "https://haveibeenpwned.com/api/v3/breachedaccount/$EMAIL" \
    -H "hibp-api-key: $HIBP_KEY" -H "User-Agent: zenonym-osint-audit"
  echo "=== ARCHIVE SNAPSHOTS ==="
  curl -s "http://web.archive.org/cdx/search/cdx?url=relay.dev&matchType=domain&output=json&fl=timestamp,original"
} > "$OUT"
EOF
$ chmod +x osint-audit.sh && ./osint-audit.sh
$ diff -u osint-20260601.txt osint-20260901.txt
The diff is the deliverable. A new line means something changed in your exposure — a new account, a new breach, a new archive capture. Empty diff means the footprint is stable.
6. Self-Audit Checklist
- Handles enumerated — every username you have used, checked across 400+ platforms, hits confirmed manually.
- Email breaches reviewed — every address listed with the exposed data classes; passwords rotated where credentials leaked.
- Dorks run — address, name + domain, and
filetype:variants, with hits classified as under-your-control or not. - Archives checked — CDX listing reviewed for every domain you have owned; exclusion requested for deleted pages.
- Brokers logged — submissions, confirmation IDs, and re-list dates recorded in one file.
- Baseline saved — audit output stored so next quarter's diff is meaningful.
- Re-audit scheduled — 90 days, plus a notification feed for breach data in between.
7. Frequently Asked Questions
Is it legal to look myself up like this?
Yes — all five tasks query public sources: search indexes, public APIs, and archive services. Nothing here accesses private data or bypasses authentication. Querying a third party's footprint with the same tools raises different questions depending on your jurisdiction and their terms of service.
How long does a full audit take?
Two to four hours for a first pass. Username and dork tasks are fast; broker opt-outs are the slow part because each is a separate form and several require email confirmation. Re-audits take about 20 minutes once the baseline and script exist.
Do I need paid tools?
No. Sherlock, Maigret, curl, jq, and the HIBP range API are free. The HIBP breach API needs a paid key for programmatic use, but the web interface and the range API for passwords are free. Paid brokers will resell you the same public records at a markup.
Will data broker opt-outs stick?
Partly. Expect the majority to hold for six to twelve months and a minority to re-list within weeks. The log-and-recheck pattern in Task 5 handles this better than trying to force permanent removal.
Sources & References
- Have I Been Pwned — API v3: https://haveibeenpwned.com/API/v3 — breach data and the k-anonymity password range API
- Sherlock: https://github.com/sherlock-project/sherlock — username enumeration across social networks
- Maigret: https://github.com/soxoj/maigret — maintained alternative with HTML reporting
- Internet Archive Wayback CDX API: https://archive.org/developers/ — historical snapshot indexing
- Google Search Operators: https://support.google.com/websearch/answer/2466433 — supported dork syntax
- OSINT Framework: https://osintframework.com/ — categorized tool index by data type
Commands in this guide were validated on Ubuntu 24.04 LTS with sherlock 0.15, curl 8.5, and jq 1.7. Each step is tested before publication. Public-record sources and broker opt-out processes change without notice — verify each endpoint before relying on it.